How Teams Can Turn One Spokesperson Video into Many Versions with AI Lip Sync
Versein Team · Updated

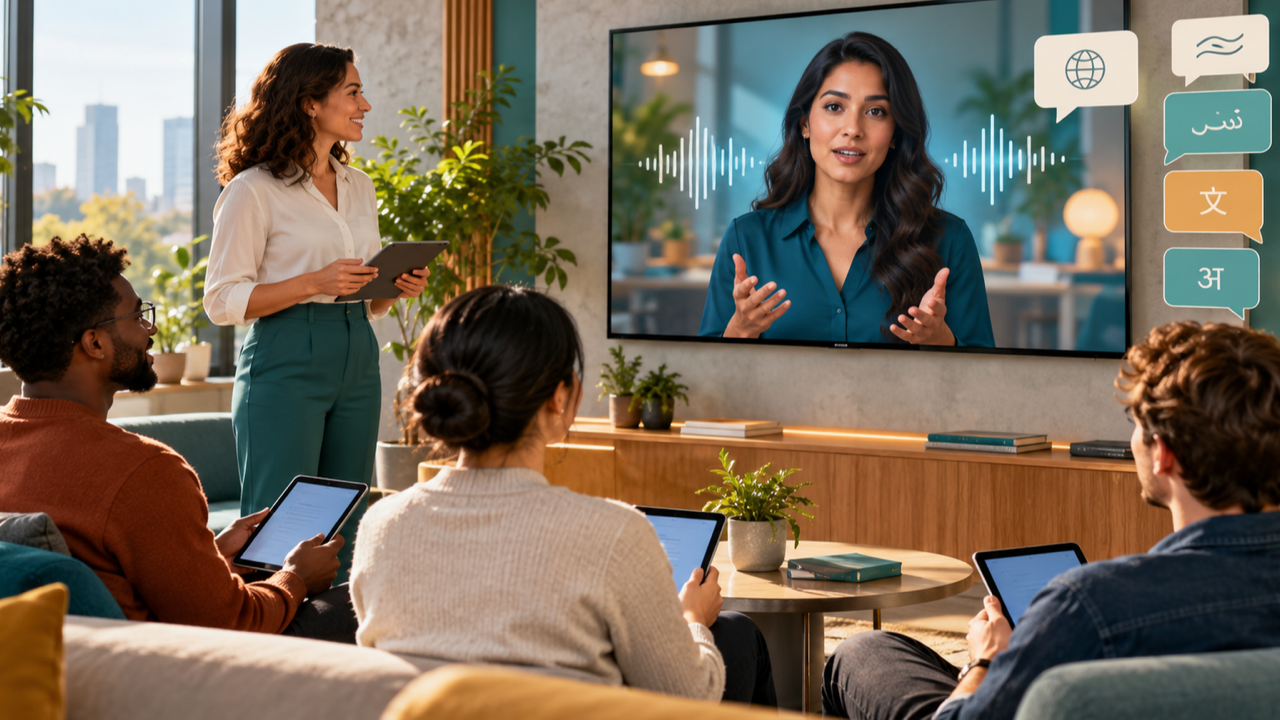
Filming an executive, brand ambassador, or product presenter takes serious time, coordination, and budget. Instead of bringing your talent back to the studio for every new campaign line, audience segment, or promotional angle, your team can use AI lip sync to match the presenter's mouth movements to entirely new audio tracks. This production method lets growth and creative teams multiply a single high-quality video shoot into an ongoing library of fresh, localized, and tested creative assets.
Key Takeaways
- AI lip sync enables teams to keep original camera framing, facial expressions, and presenter likeness while swapping the spoken script completely.
- A single master shoot can power multiple marketing angles, regional phrasing variations, seasonal campaign offers, and audience-targeted hooks.
- High-performing variations require crisp base footage, clear consent agreements, cleanly separated voice tracks, and human quality reviews.
- Scaling multiple video cuts across several teammates works best when team members have pooled resources, per-seat credit oversight, and predictable job queues.
Why Filming Separate Takes for Every Angle Fails to Scale
Creative teams face constant pressure to deliver more personalized creative across paid ads, landing pages, and email sequences. According to a HubSpot survey of 1,500+ marketers in the 2026 State of Marketing report, 83.5% of marketers say they are expected to produce more content, with 35.7% noting they need to produce much more. At the same time, traditional live-action production creates hard bottlenecks: talent availability is scarce, studio time is expensive, and tiny script edits usually require full reshoots.
When teams attempt to film dozens of script variations on set, presenters fatigue, lighting shifts across takes, and editing overhead explodes. AI lip sync breaks this dependency. By taking one master recording featuring steady lighting, clear framing, and natural facial gestures, teams can preserve the premium look of a studio shoot while generating alternative spoken messages on demand.
The Core Concept: Keep the Picture, Change the Speech
The foundational premise behind video variant generation is simple: keep the picture, change the speech. When using dedicated tools like the VerseIn AI Lip Sync tool, you provide two primary inputs:
- A source video or image with a clearly visible, unobstructed face.
- An audio track containing the new speech, such as a fresh voice-over recording, an AI-generated narration, or a translated track.
The underlying model analyzes the audio cadence, phonemes, and pacing, then redraws the mouth area of the presenter so their lip movements align naturally with the new speech. Your team can swap the audio, run the generation again, and compare the versions side by side right in your media library.
Because the process modifies mouth mechanics rather than generating an entirely synthetic human from scratch, you retain the subtle head tilts, eye contact, and authentic production value of your real presenter.
4 Practical Angles You Can Create from One Master Take
Rather than producing random clips, structured marketing teams design variants around deliberate testing hypotheses and audience journeys. Here are four common angles teams generate from a single spokesperson asset:
1. Hook and Value-Proposition Testing
The first three seconds of a social video dictate whether a viewer stays or scrolls. In paid social campaigns, swapping the initial problem statement lets performance teams test distinct emotional triggers without reshooting the entire pitch. For instance, an ecommerce brand selling productivity software can retain the presenter explaining the core dashboard while testing three different opening hooks:
- Pain-point angle: Focuses on hours lost to manual spreadsheet updates.
- Outcome angle: Highlights finishing weekly reporting before Friday afternoon.
- Cost-savings angle: Emphasizes replacing three separate recurring tool subscriptions.
By pairing AI lip sync with tools like the VerseIn AI UGC Ad Generator, marketers can rapidly test alternative hook narratives against a shared visual foundation.
2. Segment-Specific Offers and Calls to Action
Different buyer personas care about different incentives. An enterprise buyer looks for security and onboarding assurances, while an individual practitioner wants quick setup and self-serve utility. Teams can record a general product walk-through once, then use lip sync to modify the closing call to action:
- Version A points prospects to a live interactive demo.
- Version B invites viewers to start an instant 14-day trial.
- Version C delivers a limited-time coupon code aimed at retargeting audiences.
Modifying just the spoken offer ensures every viewer receives a relevant next step without forcing your video production team to edit three separate live-action takes.
3. Regional and Tone Variations
Different markets often respond to distinct communication styles, even when speaking the same broader language. A video scripted for North American audiences might feel too direct or use unfamiliar terminology for viewers in the United Kingdom or Australia.
Teams can adapt the underlying script to adopt local phrasing, generate or record regional voice tracks using the VerseIn Voice Over tool, and apply lip sync to align the presenter's lips with the regional script. If your team needs to translate content into completely different languages, pairing lip sync with automated localization pipelines like the VerseIn AI Video Dubbing tool ensures the foreign-language audio tracks match the original presenter's face.
4. Time-Sensitive Campaign and Seasonal Updates
Studio videos quickly become outdated when pricing tiers update, seasonal holidays approach, or promotional calendar dates shift. Instead of retiring a spokesperson video that took thousands of dollars to produce, you can update specific sentences describing current deadlines or seasonal packages. Rerunning the audio track through lip sync keeps evergreen footage relevant across multiple quarters.
Step-by-Step Workflow: Transforming One Take into Multiple Cuts
To achieve clean, natural results that avoid awkward visual artifacts, teams should follow an orderly production pipeline from studio capture to final export.
Step 1: Capture the Master Footage with AI in Mind
High-quality input footage directly determines how realistic your final lip-synced output looks. When recording your spokesperson on set, follow these technical guidelines:
- Maintain steady lighting: Ensure the lower half of the subject's face has balanced, even lighting without heavy, moving shadows across the jawline.
- Avoid face obstructions: Instruct talent to avoid gesturing with their hands near their mouth, chin, or cheeks. Microphones, props, or coffee mugs should stay well outside the mouth region.
- Keep head motion natural but controlled: Extreme profile angles or rapid back-and-forth head swinging can cause tracking issues. A confident, forward-facing presentation works best.
- Record in a neutral room: Keep background noise minimal so that the initial camera audio can be cleanly replaced or referenced without bleed.
Step 2: Draft and Refine Alternative Script Variations
When writing alternative audio scripts for an existing video, match the length and pacing of the original take as closely as possible. If the spokesperson takes five seconds to deliver a line on camera, writing a replacement line that requires twelve seconds of rapid speech will force artificial pacing.
Draft your alternative scripts side by side with the video timeline. Read the new lines aloud while watching the muted video to confirm that breath pauses and natural emphasis align with the presenter's physical body language.
Step 3: Produce Clean, Consistent Audio Tracks
Before uploading files to the lip sync tool, make sure your audio assets are crisp and isolated. You can produce replacement tracks by recording voice talent in a studio or generating narration through an AI voice tool.
Ensure that:
- The audio contains spoken dialogue only, without background music or sound effects mixed in (add background scores later during final post-production).
- Voice tone, volume levels, and emotional intensity match the physical energy the spokesperson displays on screen.
- Audio file durations correspond neatly to the visual cuts you plan to sync.
Step 4: Run Generations and Compare Side by Side
Upload your base video along with your primary replacement audio into your project workspace. In tools like the VerseIn AI Lip Sync tool, you simply attach the video or image featuring a clear face, select your audio file, and initiate the generation.
Once processing finishes, the generated video saves directly into your personal Media library. To build out your testing matrix, upload your remaining alternative audio tracks, run them against the same visual master, and compare the resulting takes side by side to verify sync accuracy and mouth movement realism.
Step 5: Finish with Captions, Aspect Ratios, and Post-Production
After locking in your preferred lip-synced cuts, finalize the assets for distribution across social and advertising platforms:
- Add styled captions: A large share of mobile feeds are browsed on mute. Running your finished video through the VerseIn AI Captions tool generates editable, timestamped transcripts and subtitle overlays that keep videos engaging without sound.
- Reframe for multiple ad placements: If your master cut was filmed in landscape (16:9), adapt the asset for vertical channels (9:16) like TikTok, Instagram Reels, and YouTube Shorts using tools within VerseIn Marketing Studio.
- Layer background music: Bring the lip-synced video into your editing suite to place subtle background tracks and sound effects beneath the clear vocal track.
| Stage | Key Focus | Recommended Input / Tool |
|---|---|---|
| Master Capture | Clean lighting, unobstructed mouth, forward posture | High-definition camera, neutral studio |
| Audio Generation | Matched pacing, isolated vocal audio, consistent tone | Voice recording or VerseIn Voice Over |
| Lip Synchronization | Aligning mouth mechanics to new audio cuts | VerseIn AI Lip Sync |
| Finishing & Captions | Silent browsing accessibility and social ratios | VerseIn AI Captions & Marketing Studio |
Quality Checklist: What Reviewers Must Inspect
Because lip synchronization modifies the visual integrity of a human face, creative directors and compliance reviewers should inspect every variation before publication. Use this checklist during review rounds:
- Mouth-to-audio sync: Do plosive consonants (such as "p", "b", and "m") align tightly with closed-lip frames on screen?
- Teeth and jaw realism: Does the boundary between the lips, teeth, and chin remain sharp, without visual blurring or melting artifacts?
- Expression continuity: Does a serious, analytical script sound odd over footage where the presenter is smiling broadly, or vice versa?
- Audio clarity: Is the voice free from background hum, distortion, or abrupt clipping at the beginning and end of sentences?
- Claim verification: Have all factual statements, promotional discount codes, and product guarantees in the new script received marketing and legal approval?
- Platform compliance: Does the final video comply with advertising guidelines regarding digital likeness disclosures where applicable?
Managing Video Variant Workflows Across a Marketing Team
As ad testing accelerates, multiple team members often generate variations simultaneously. A copywriter might draft five new hook scripts, a performance marketer might queue the audio files, and a video editor might review the final outputs.
Managing this workload on disjointed individual accounts leads to fragmented media files and unexpected credit bottlenecks. When teams upgrade their infrastructure, collaborative management becomes critical.
For high-volume creative operations, the VerseIn Teams & Business plan addresses these collaboration challenges directly. The plan lists unlimited members, allowing every contributor to operate under their own individual account within a single organization rather than sharing fragile login credentials.
Additionally, the Teams & Business plan lists:
- A shared team pool of custom monthly credits, backed by centralized admin control with per-user credit usage, permissions, and credit limit controls to keep projects under budget.
- Custom concurrent generations with priority queue, ensuring heavy batch processing jobs wait in an orderly queue rather than blocking urgent team workflows.
- Workspace model restrictions, which let administrators restrict workspace members to specific models to ensure brand consistency and cost governance.
- Volume-based discounts, premium 24/7 customer support, and early access to advanced AI features, along with generous discounts and premium benefits for watermark-free, high-resolution exports detailed in the quote.
To request details and discuss sizing for your organization, use the Contact Us button on the pricing page or email [email protected] with the subject "VerseIn Teams Plan Inquiry".
Ethical Guidelines and Consent for Spokesperson Modifications
Modifying a real person's speech using synthetic media requires transparent ethical guardrails. Never make a real person appear to say something they have not explicitly approved.
When contracting with on-screen talent, actors, or internal team spokespeople, incorporate clear usage agreements:
- Obtain written likeness consent: Ensure talent agreements explicitly cover AI voice pairing, translation, and lip-synchronization for marketing purposes.
- Maintain script approval processes: Provide talent or their representatives with visibility into the types of scripts and claims their likeness will represent.
- Store source assets securely: Protect raw video takes and voice models to prevent unauthorized tampering or unapproved internal use.
Adhering to strict consent practices protects your brand reputation while fostering long-term trust with creative talent.
FAQ
What happens if an AI lip sync generation fails?
If a video generation encounters a processing error, timeout, or fails a content safety check on VerseIn, your generation credits are returned to your account balance automatically. You will always see the total credit cost displayed before confirming any generation.
Can I use AI lip sync on a still photo instead of a video?
Yes. The lip sync tool accepts either a pre-recorded video or a high-resolution still image with a clearly visible face. When syncing an image to an audio track, the model animates the facial features and mouth movements to deliver a talking-photo presenter clip.
How do I keep the presenter's voice consistent across different script versions?
To ensure the presenter sounds identical across multiple scripts, you can clone the presenter's original voice using the voice-over tools (provided you have the individual's written consent) or record all new script lines with the same voice actor before running the lip sync tool.
What kind of video footage delivers the most realistic lip sync results?
Footage featuring steady studio lighting, a direct front-facing camera angle, minimal facial obstruction, and natural, relaxed speech pacing yields the highest quality results. Avoiding rapid head movements or hands crossing in front of the mouth ensures clean tracking.
Are lip-synced videos generated on VerseIn allowed for commercial advertising?
Yes. Paid plans allow commercial use under VerseIn's terms of service, provided your source footage complies with consent rules and does not use a real person's likeness without explicit permission. Paid subscriptions also export final videos without a visible watermark.
Sync Spokesperson Videos to Any Audio Track
Turn one clean talking-head take into dozens of audience-specific video variations in minutes.